Rohan Paul (@rohanpaul_ai) · 2026/10/14 17:52:33
ServiceNow 与麦吉尔大学发布 AgentHorizon:LLM 裁判在长程计算机任务中漏检细微错误,工具辅助反而降低准确率
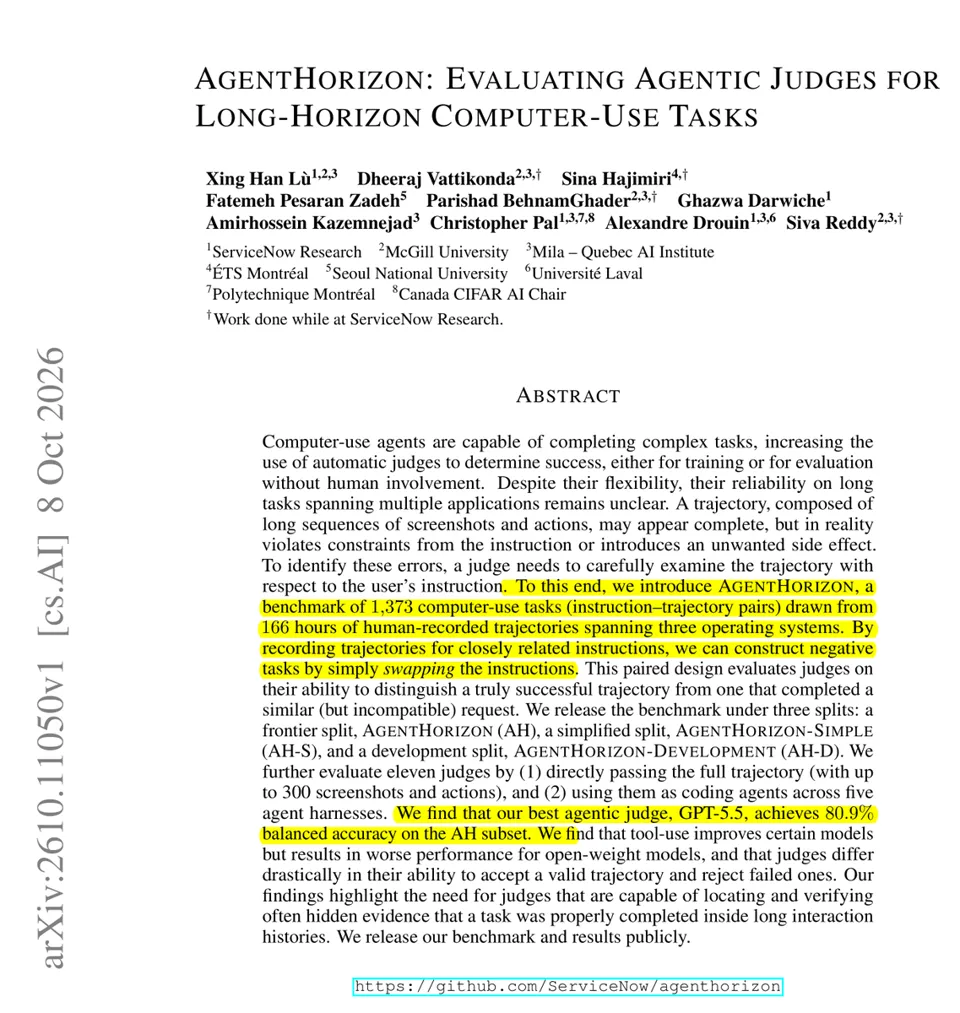
ServiceNow 与麦吉尔大学联合推出 AgentHorizon 基准测试,包含 1373 个基于人类屏幕录制的评判任务,专门用于检测 AI 代理在长程操作中的“近似失败”(如画错形状或发错频道)。研究发现,即便是表现最佳的 GPT-5.5 在困难子集上的平衡准确率也仅为 80.9%,且为 Qwen 3.6 等模型提供工具辅助反而使其从直接读取的 77.6% 降至 70.4%,表明当前 LLM 作为自动评估器在处理复杂、多步计算机使用场景时仍存在显著盲区。
报道全文原始报道全文
Rohan Paul (@rohanpaul_ai) · 2026-10-14 09
New ServiceNow and McGill paper finds that AI judges still miss subtle mistakes in long computer-use tasks, and giving them tools does not reliably help.
Teams use LLMs to grade agent runs for training and evaluation. A run of 100+ steps can look finished while it drew the wrong shape or posted to the wrong Slack channel.
They built AgentHorizon, 1,373 judging tasks from human screen recordings. People recorded pairs of near-identical tasks and swapped the instructions, so each failure is a clean run of a slightly different request.
The best judge, GPT-5.5 in Codex, scored 80.9% balanced accuracy on the hard split, where always saying yes gets 50%. Qwen 3.6 27B did worse with tools, scoring 77.6% reading the whole run directly but 70.4% as an agent.
Before you trust an LLM judge with agent runs, test it on near-miss failures inside the exact agent setup you will use.