Thinking Machines Ships Inkling 2 Small, a 594B Sparse MoE Model
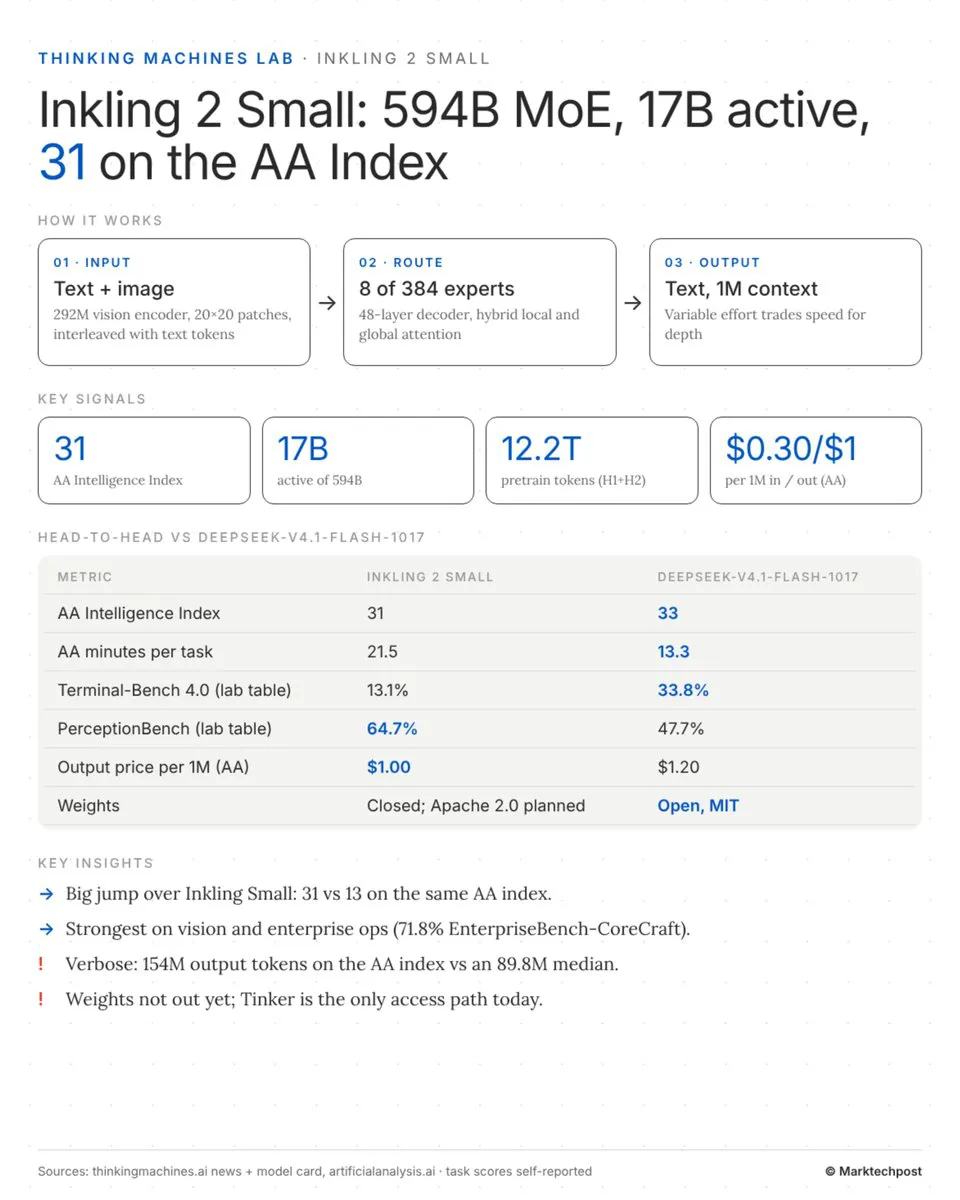
Thinking Machines Lab released Inkling 2 Small, a 594B-parameter Mixture-of-Experts model that activates only 17B parameters per token, routing each token to 8 of 384 experts across 48 layers with a 292M vision encoder for image input. It scores 31 on the Artificial Analysis Intelligence Index and 86.3% on SWE-Bench Pro v2, but is slow per task and weak on Terminal-Bench at 13.1%; weights remain closed with an Apache 2.0 release planned after safety testing.
Full Report
▲ Marktechpost AI · 2026-11-06 04
▲ Thinking Machines Lab just shipped Inkling 2 Small, a 594B Mixture-of-Experts model that only fires 17B parameters per token.
The key idea is a large expert pool at a small active cost. Each token routes to 8 of 384 experts across 48 layers. A 292M vision encoder feeds image patches straight into the same decoder.
It scores 31 on the Artificial Analysis Intelligence Index, up from 13 for Inkling Small. DeepSeek-V4.1-Flash-1017 scores 33 and GLM-5.3-Flash scores 28. It posts 86.3% on SWE-Bench Pro v2 (Hard) and 64.7% on PerceptionBench. It is a trade-off though: it takes 21.5 minutes per AA index task and hits only 13.1% on Terminal-Bench 4.0.
It runs on Tinker today for fine-tuning and inference at 1.00 per 1M tokens. Weights are closed for now, with an Apache 2.0 release planned after safety testing......
Full analysis: