Rohan Paul (@rohanpaul_ai) · 10/21/2026, 03:39:01
OXR Releases Open-Source Document Parser with RSI Training Loop
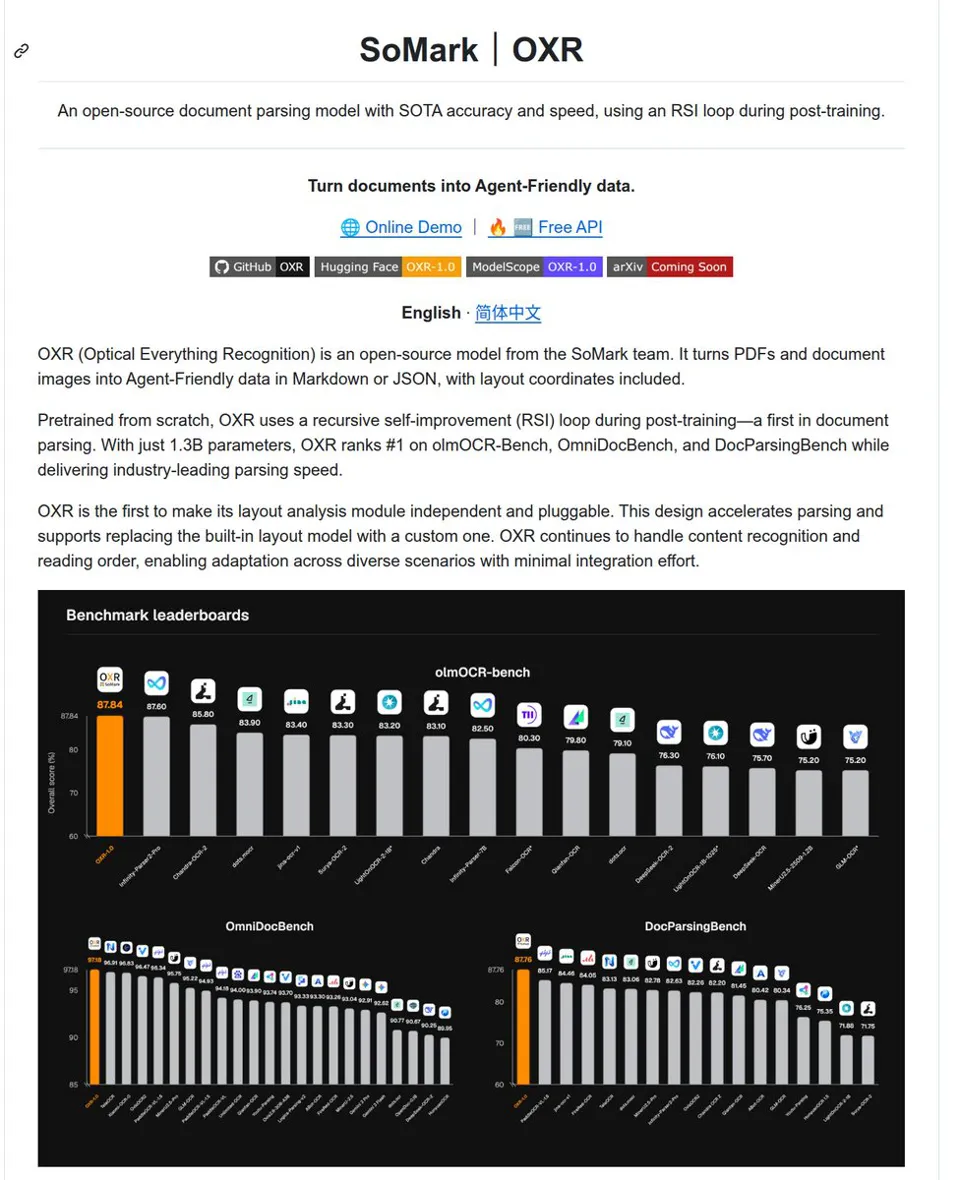
OXR releases a 1.3B-parameter open-source document parser that pioneers Recursive Self-Improvement (RSI) in OCR training. By using VLMs to evaluate outputs and cluster failure causes for targeted data generation, the model tops olmOCR-Bench, OmniDocBench, and DocParsingBench while achieving 3.05x the throughput of GLM-OCR on a single RTX PRO 6000.
SOURCE COVERAGEFull Original Report
Rohan Paul (@rohanpaul_ai) · 2026-10-20 19
OXR makes parsing failures part of the training process.
During post-training (OXR is the first document parser to use RSI here), a VLM evaluates its outputs, rollout disagreements flag uncertainty, and a separate clustering model groups the causes;
those findings then guide targeted data generation for the next round, and the 1.3B model that comes out of it sits first on olmOCR-Bench, OmniDocBench and DocParsingBench while running 3.05× GLM-OCR's throughput on a single RTX PRO 6000, the fastest open-source result in the speed comparison.
Worth studying (Github link in comment)
↳ 引用 @somarkai (SoMark): Beyond OCR. Meet OXR. Only 1.3B. Open source.
#1 on olmOCR-Bench, OmniDocBench & DocParsingBench🏆 #1 in parsing speed among open-source models⚡
RSI-powered. A first in document parsing. Turn documents into Agent-Friendly data.
If OXR helps, give us a star on GitHub! 🌟