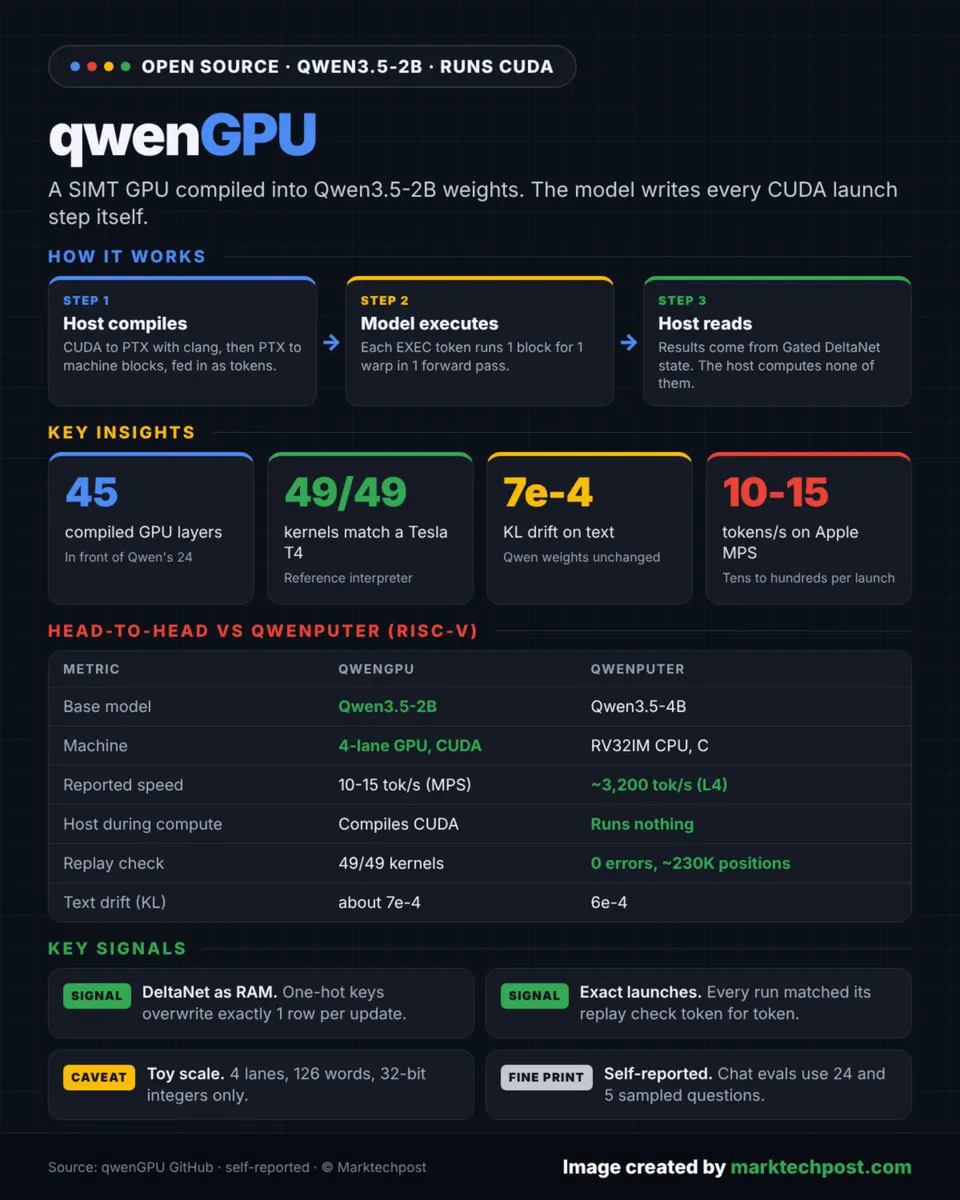
qwenGPU Embeds a SIMT CUDA Core Inside Qwen3.5 Weights
Developer project qwenGPU compiles a 45-layer SIMT architecture directly into Qwen3.5-2B weights, enabling the model to execute real CUDA instructions internally. By repurposing Gated DeltaNet states as memory, it achieves high kernel fidelity on Tesla T4 hardware despite slower inference speeds and minor text drift.
Full Report
▲ Marktechpost AI · 2026-11-02 07
▲ [Really Impressive Individual Project] Meet qwenGPU: Qwen3.5-2B With 45 Compiled GPU Layers That Run CUDA. qwenGPU, a SIMT GPU compiled directly into the weights of Qwen3.5-2B. The model runs real CUDA inside its own forward passes.
The key idea is reusing Qwen3.5's Gated DeltaNet state as GPU memory. With the gate held open, a write strength of 1 and one-hot keys, each update overwrites exactly 1 row. Registers, program ROM and global memory all live in those rows.
The GPU is 45 untrained layers in front of Qwen's 24: 4 lanes, a 4-stage pipeline, 15 registers per lane and 126 words of memory. The reference interpreter matched a real Tesla T4 on 49 of 49 kernels, and text drift stays at a KL of about 7e-4. It is a trade-off though: it runs at about 10 to 15 tokens per second on Apple MPS, and Qwen-written CUDA was right on 4 of 5 tries.
The code is MIT, and you build the checkpoint yourself with about 16 GB of free memory. It builds on Qwenputer, which put a RISC-V CPU inside Qwen3.5-4B......
Full analysis: